Website comparisons
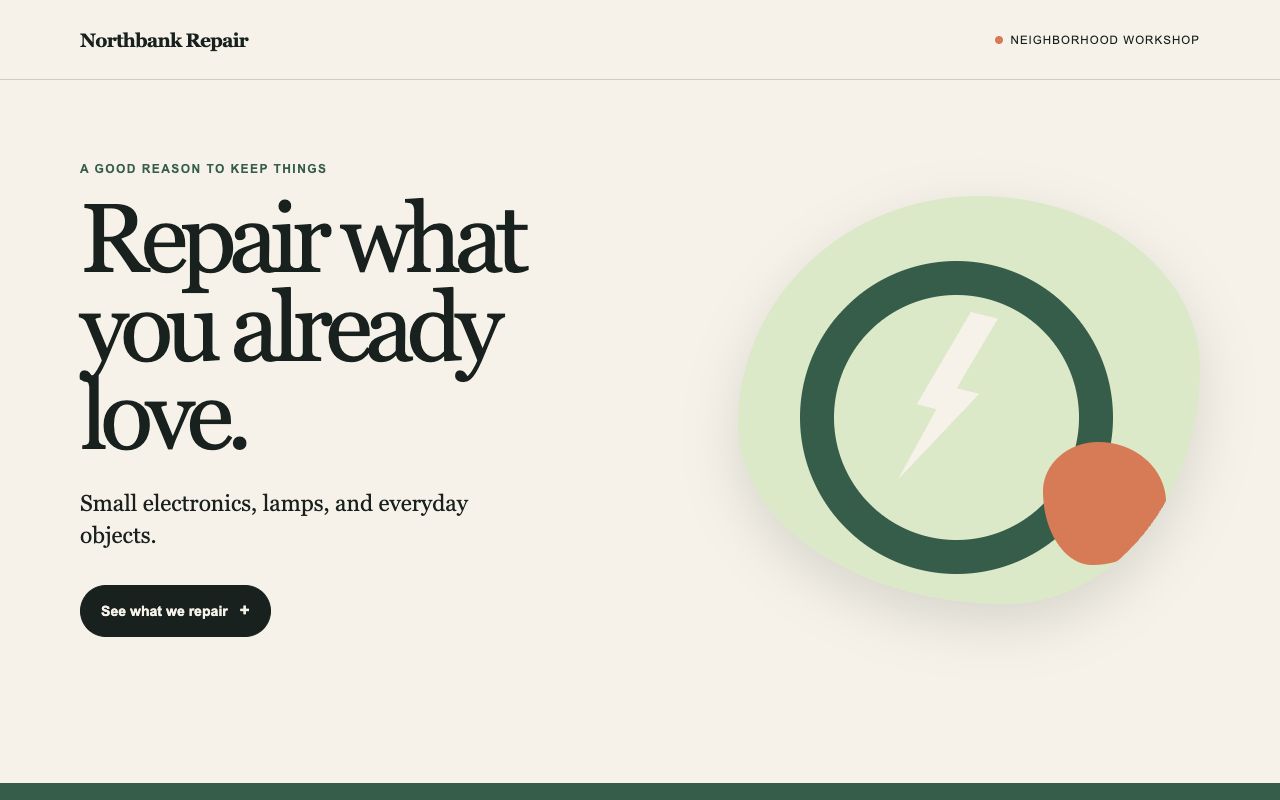
Northbank Repair website
How does the same repair-workshop brief change when exclusions or a concrete editorial direction are added?
2 pairs
AI Slop / Website comparisons
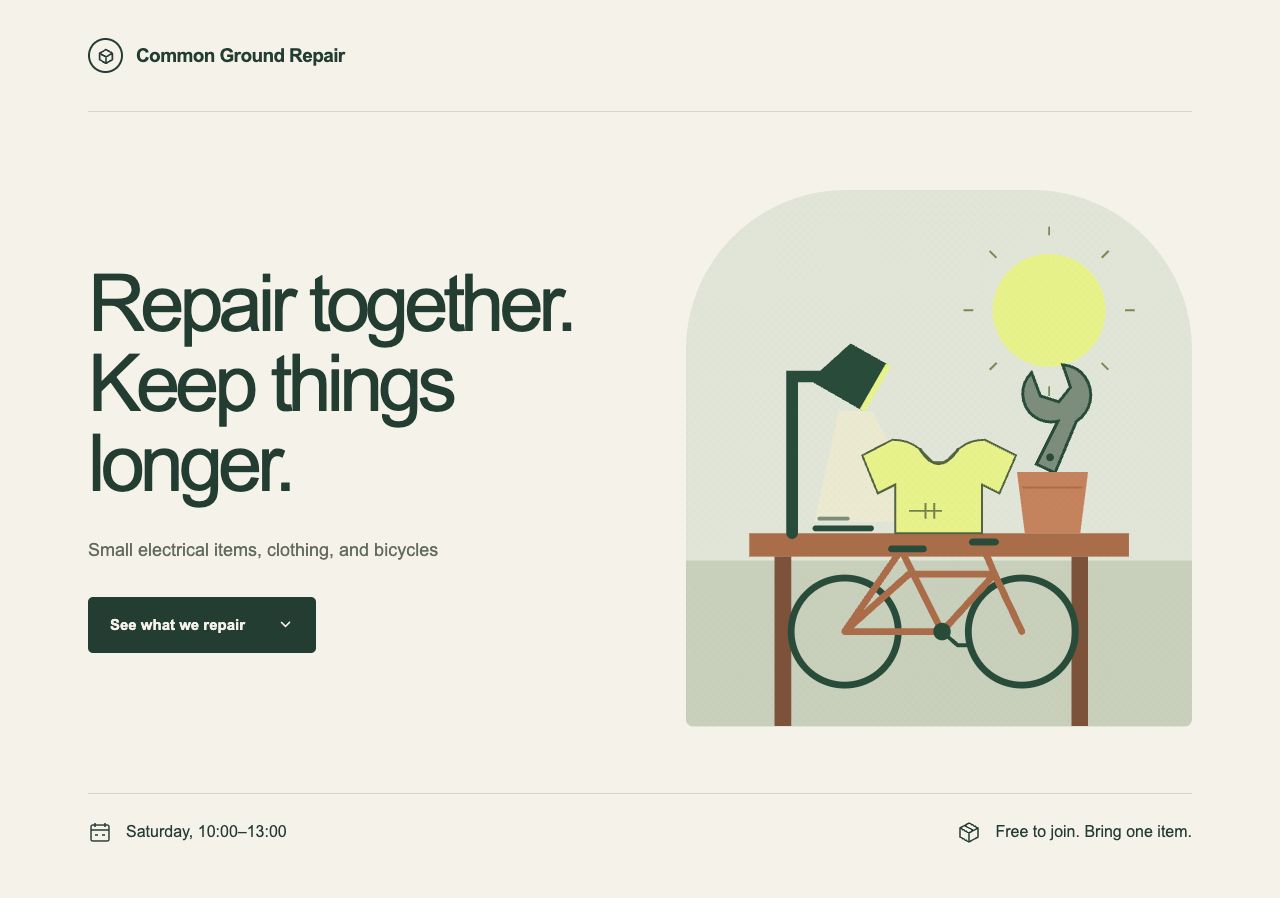
What do the first outputs look like when gpt-6.1-sol receives the same brief with low and high reasoning?
Open preserved archive ↗Model, prompt bytes, sandbox and tools instruction match, but each setting has one sample. Seeds, service snapshot and internal budget are unknown. Changing effort is explicit; the pair cannot establish a stable causal effect or ranking.
Kumyu · preserved AI Slop archive
Recorded original outputs; external source material remains linked to its publisher
This comparison preserves actual independent outputs. Each run has its own settings and timestamps; expand the run records beside this note or open the complete preserved comparison.
Website comparisons
How does the same repair-workshop brief change when exclusions or a concrete editorial direction are added?
Choose two works to see their actual outputs and records side by side.
Open comparison ↗